Microsoft Outage: Why Outlook and Teams Went Down for Over 24 Hours
Explore the November 2026 Microsoft outage timeline, its network-related cause, global impact on Outlook and Teams, and how Microsoft restored services.
Latest Story
On the afternoon of 12 November 2026, UTC, Microsoft’s cloud email system began to fail. Within an hour, people in 74 countries were reporting that Outlook would not open. Teams calendars broke, Copilot lost access to mail, airlines lost their email help desks, a British court sent its jury home and governments from Singapore to Norway lost ministry email. The Microsoft outage ran for well over 24 hours before Microsoft announced, early on 14 November, that service was restored. The cause, the company said, was not hackers or a surge of users but a fault left behind by its own network-capacity upgrade.
This is a timeline of the November 2026 Microsoft 365 outage, with earlier Microsoft outages and the July 2024 CrowdStrike crash kept apart at the end for comparison. The cause and recovery steps come from Microsoft’s own status updates as reported by CNBC, AP, Al Jazeera and others; no independent investigation has been published. Outage-report figures are complaints, not counts of people. Where the brief we worked from had a detail we could not confirm, we say so in the entry.
💡 Short Answer
The November 2026 Microsoft outage began at 16:17 UTC on 12 November, when Exchange Online started failing, and spread to Outlook, Teams calendars, Copilot and other Microsoft 365 services worldwide. Microsoft blamed a problem from an earlier network-capacity upgrade, exposed by a later network change, and ruled out a cyberattack. It announced restoration on 14 November.
Microsoft Outage: Key Questions
The Outage in Ten Points
- Start: Exchange Online began failing at 16:17 UTC on 12 November 2026, first for users in the Americas.
- Spread: reports came from 74 countries within about an hour, peaking at 19,650 a minute.
- Services: Outlook, Teams calendars, Copilot, SharePoint Online, OneDrive and Intune were all hit.
- Cause: a fault from an earlier network-capacity upgrade, exposed by a later network change.
- Mechanism: servers failed automated health checks, dropped out and left the rest overloaded.
- Not traffic, not hackers: Microsoft corrected its early “elevated load” line and ruled out a cyberattack.
- The fix: a new health-check method, a rollback, a routing patch, staged reboots and a 48-hour email timeout.
- Impact: airlines, the NHS, pharmacies, courts, police, banks and several governments switched to backups.
- Restored: Microsoft announced recovery early on 14 November and apologised.
- Not CrowdStrike: the July 2024 crash was a third-party update on Windows PCs; this was Microsoft’s own cloud.
The 36 Hours, at a Glance
From the first failed mailbox to Microsoft’s all-clear.
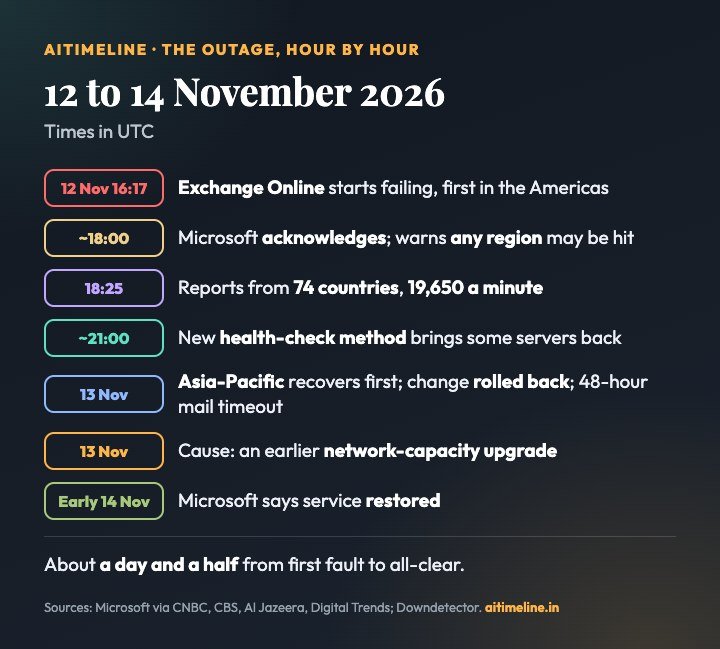
The pattern is familiar to anyone who runs large systems. A fault sits unnoticed after an upgrade. A later, routine change triggers it. Automated safety checks then make things worse by pulling servers out of service, which piles more work onto the servers that remain until they fail too. Most of the outage’s length came not from finding the problem but from bringing capacity back without knocking it straight over again.
What Caused the Microsoft Outage?
Microsoft’s explanation, step by step.
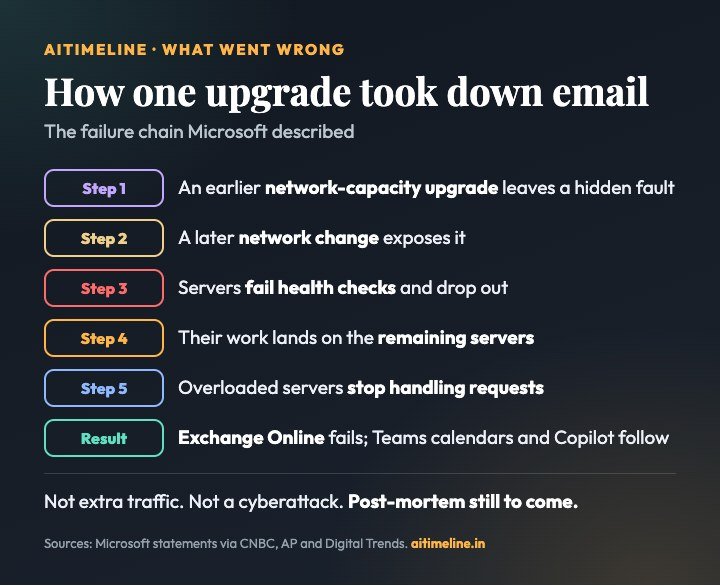
- A hidden fault: an earlier network-capacity upgrade introduced a problem that did not show up at the time.
- A trigger: a more recent network change exposed it.
- Servers drop out: a number of Exchange Online servers failed automated health checks and became unavailable.
- Load piles up: their work shifted onto the remaining servers, which became overloaded.
- Requests fail: overloaded servers could not reliably process connections, so mailboxes would not open.
- Knock-on effects: Teams calendars, Copilot and other services that depend on Exchange Online failed with it.
Two things Microsoft did not say matter as much as what it did say. It has not named the upgrade or the later change, or said when either happened. And early reports, including the brief we worked from, described a specific process for handling secure connections becoming overwhelmed; we could not find that in any report we were able to read, so we leave it out. The company’s own post-mortem should settle these details.
Which Microsoft Services Were Affected?
Anything that needed a mailbox was most at risk.
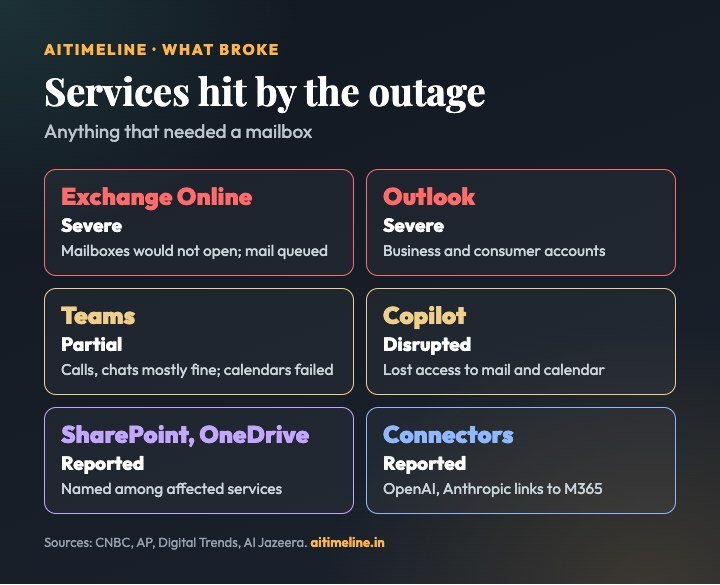
| Service | What users saw |
|---|---|
| Exchange Online | Mailboxes would not open; mail could not be sent or received; queues built up |
| Outlook (business and consumer) | Could not connect or load mail; Microsoft’s dashboard showed degradation across consumer services too |
| Microsoft Teams | Calls, meetings and chats mostly worked; calendar and scheduling tasks could fail |
| Microsoft 365 Copilot | Disrupted, especially where it needed mail or calendar data |
| SharePoint Online, OneDrive, Intune | Named among affected services in reports |
| Third-party connectors | OpenAI and Anthropic reported problems connecting to Microsoft 365 tools |
Timeline: The Microsoft Outage, 12 to 14 November 2026
Newest first, with earlier Microsoft outages at the end. Colour shows the track.
Where things stand The outage
Settled: Microsoft says it has fixed the underlying issue and restored service to the remaining affected customers and regions. It says the cause was technical, not a cyberattack.
Not settled: Microsoft has not yet published its post-incident review. Until it does, the exact engineering sequence rests on the company’s own status updates and press reports. Some delayed mail and connected features may take longer to settle.
Microsoft says service is restored Microsoft says
What it said: “We have completed our efforts to address the underlying issue of the incident and restored service to the remaining impacted customers and regions.” Further updates were posted under incident MO1550821 in the Microsoft 365 admin centre, according to Digital Trends.
How to read it: This is the company’s own statement. Some outlets headlined it as “fully restored”; Microsoft’s wording was about the “remaining impacted” customers and regions. PTC News reported that Microsoft kept updating its list of affected services for some hours afterwards.
An apology, and a promised post-mortem Microsoft says
What Microsoft said: A spokesperson said the company was “deeply sorry for the disruption this incident has caused our customers and partners.” Lamanna said recovery had been “more difficult than normal” because of “technical challenges and failure modes”, and promised a post-mortem with a step-by-step timeline and repair items.
In India: Puneet Chandok, president of Microsoft India and South Asia, wrote on LinkedIn: “We regret the disruption today’s outage has caused for many of our customers.”
The cause: a network-capacity upgrade Microsoft says
What Microsoft said: The problem had been introduced during an earlier network-capacity upgrade and surfaced after a more recent network change. Servers that became unavailable left the rest carrying more load than they could handle.
What it corrected: Microsoft’s first updates spoke of “elevated load” and, per CNBC, a traffic surge. It later said the load had not been caused by an increase in traffic.
Patches, reboots and a rollback Engineering & recovery
What engineers did: On Friday Microsoft said it was rolling back a network change and checking that “developed patches have been applied and working as intended after infrastructure reboots are completed.” Digital Trends reported a patch to an authentication and routing component.
Why it was slow: Restarted servers became unresponsive again once traffic returned, so services had to be brought back in stages. Microsoft described its early progress as “marginal success”.
Asia-Pacific recovers first; mail queues shrink Engineering & recovery
What happened: Asia-Pacific services were among the first to normalise. By Friday Microsoft said email queues were “approaching normal levels”, and around 10:30 am ET it reported “encouraging recovery progress”.
Protecting mail: Microsoft extended the timeout window for delayed messages to 48 hours so that queued email would not be dropped while servers came back.
Teams: Calls, chats and channel messages mostly worked. Calendar tasks that depend on Exchange Online could still fail.
Asia and Europe wake up to the outage Global fallout
Scale: By about 07:00 GMT on Friday Downdetector had at least 43,000 reports of Outlook problems from users in 72 countries, Al Jazeera reported, calling it a partial picture.
Governments: Singapore’s GovTech said government email was down. Japan’s government said its IT systems were affected. The Philippines’ Supreme Court said email responses were affected. In Australia, agencies including the Australian Federal Police were hit; Greece and Norway also reported effects, according to AP.
A comparison: Australia’s Home Affairs Minister Tony Burke said Microsoft believed it was dealing with something “in some ways similar to” the CrowdStrike incident, “an update that has gone awry.” That was his summary, not Microsoft’s.
Indian airlines lose email support Global fallout
What happened: IndiGo said its email support was affected and pointed customers to its virtual assistant. Akasa Air reported delays and directed passengers to its 24/7 call centre and social media. Air India temporarily rerouted its email so customer messages still reached it.
What was not affected: Air India said flights were operating normally. Unlike July 2024, we found no reports of check-in systems failing at Indian airports.
Hospitals, pharmacies, police and courts in the UK Global fallout
Healthcare: The NHS used alternative systems and told patients to attend appointments as normal. The National Pharmacy Association warned of medication delays because doctors could not always email prescriptions to pharmacies.
Police and courts: A British police force said it could not receive online crime reports and asked people to phone instead. A trial in Manchester was halted when the judge sent jurors home.
A new health-check method Engineering & recovery
What happened: Microsoft said it had “validated an alternative service health check method” that brought some affected servers back online, and was “now applying this change more broadly”. It was also preparing automated systems to detect and restart unresponsive servers.
Why it mattered: Servers had been dropping out after failing automated health checks. A different way of checking them was the first step that put capacity back.
“No indication” of a cyberattack Microsoft says
What Microsoft said: “There is no indication this is the result of malicious or cyber activity.” Microsoft later told AP the outage was not related to cyber activity or to AI agents.
Why it mattered: Outages invite speculation about hacking. Unavailable is not the same as breached, and Microsoft has not reported any breach of customer data.
Reports spread to 74 countries in an hour The outage
Scale: Outlook reports began climbing at about 17:25 UTC. Within about an hour they came from 74 countries and territories, and by 18:25 UTC reports across five Microsoft services were arriving at 19,650 a minute, Downdetector said. CBS counted more than 130,000 reports on Thursday; Digital Trends later put the worldwide total above 7.4 million.
Read with care: These are complaints logged on a website, not a count of people affected. One person can report several times, and many affected users never report at all.
Microsoft acknowledges the problem Microsoft says
What happened: Microsoft first said it was investigating problems for users in the Americas, then warned that users in any region could be affected. A wider Microsoft 365 incident was logged at 1:26 pm ET, Digital Trends reported.
Early explanation: Its first updates blamed “elevated load across multiple regions” caused by “a number of servers being unexpectedly unavailable”, with some failing automated health checks.
Exchange Online starts failing The outage
What happened: Users, first in the Americas, could not open Exchange Online mailboxes. Exchange Online is the cloud email and calendar system behind business Outlook, and much of Teams scheduling and Copilot’s access to mail depends on it.
What followed: Problems spread to Outlook, Teams calendars, Copilot, SharePoint Online, OneDrive and Intune, across business and consumer accounts.
A 10-hour Microsoft 365 outage in North America Earlier outages
What happened: Microsoft 365 services were disrupted for nearly 10 hours. Microsoft linked it to elevated load after capacity was reduced during maintenance on part of its North American infrastructure.
Why it matters: It was the same family of fault as November: too little working capacity behind Exchange Online, with knock-on effects for everything that depends on it.
Azure Front Door configuration change Earlier outages
What happened: An inadvertent configuration change to Azure Front Door, Microsoft’s global content-delivery and routing service, disrupted Azure, Microsoft 365 and Xbox services and customers’ own sites. Microsoft rolled back to a last known good configuration.
Why it matters: Another case of one change in shared network infrastructure taking down many services at once.
Azure hit by a DDoS attack Earlier outages
What happened: A distributed denial-of-service attack triggered Microsoft’s defences, and Microsoft said an error in how those defences were implemented amplified the impact rather than limiting it. Some Azure and Microsoft 365 services were affected.
Contrast: Unlike November 2026, this one began with malicious traffic.
CrowdStrike: 8.5 million Windows PCs crash Earlier outages
What happened: A content update for CrowdStrike’s Falcon security sensor made Windows computers crash to the blue screen. Microsoft estimated 8.5 million devices were affected, under 1% of Windows machines. Airlines, hospitals, banks and broadcasters were hit; in India, airports went to manual check-in.
The cause: CrowdStrike’s root-cause analysis of 6 August 2024 found a mismatch between the 21 input fields its sensor expected and the 20 a content update supplied, causing an out-of-bounds memory read.
Outlook and OneDrive under DDoS attack Earlier outages
What happened: Microsoft said a group it tracks as Storm-1359 ran layer-7 denial-of-service attacks that briefly disrupted Outlook on the web, OneDrive and the Azure portal. It said there was no evidence customer data was accessed.
Contrast: This was an attack. November 2026 was not.
A router change takes down Teams and Outlook Earlier outages
What happened: Microsoft said a change to an IP address on a wide-area-network router caused packets to be forwarded wrongly across its network, disrupting Teams, Outlook and Azure for users worldwide. It rolled the change back.
Why it matters: The closest precedent for November 2026: an ordinary network change inside Microsoft, not an attack, with global effects.
Who Was Hit, Around the World
Email is plumbing. When it stopped, so did a lot of work.
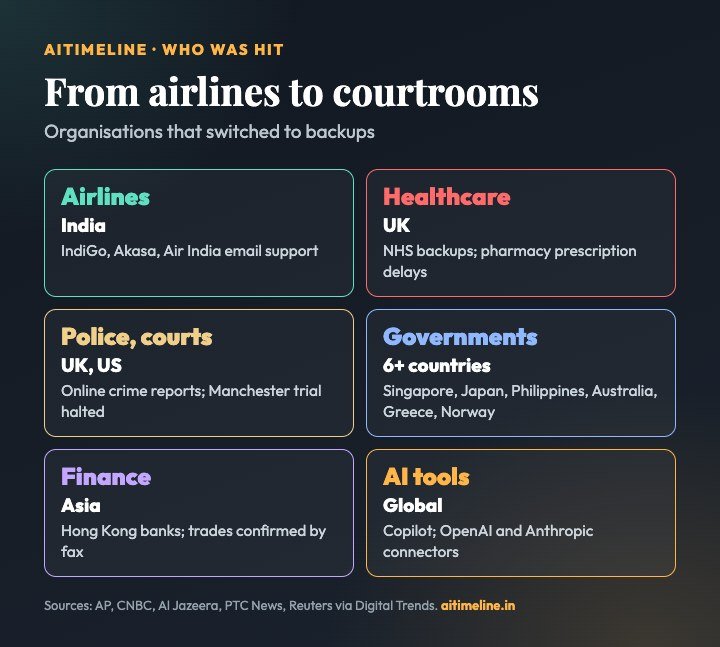
- Airlines: IndiGo, Akasa Air and Air India lost or rerouted email support; flights were not affected.
- Healthcare: the NHS used alternative systems; the National Pharmacy Association warned of medication delays because prescriptions could not always be emailed.
- Police and courts: a British police force asked people to phone in crimes; a Manchester trial was halted; Arapahoe County in Colorado could not take online bond payments.
- Governments: Singapore, Japan, the Philippines’ Supreme Court, Australian agencies, Greece and Norway reported effects.
- Finance and business: Hong Kong banks saw disruption, a Taiwanese firm confirmed trades by fax, and Richemont and Workhorse Group delayed earnings materials.
- AI tools: Copilot was disrupted, and OpenAI and Anthropic reported problems with their Microsoft 365 connections.
The brief we worked from also mentioned a large Indian brokerage that kept Outlook running on backups but struggled with client calls over Teams. We could not find that report, so we have left it out.
How Big Was the Outage?
Big numbers, read carefully.
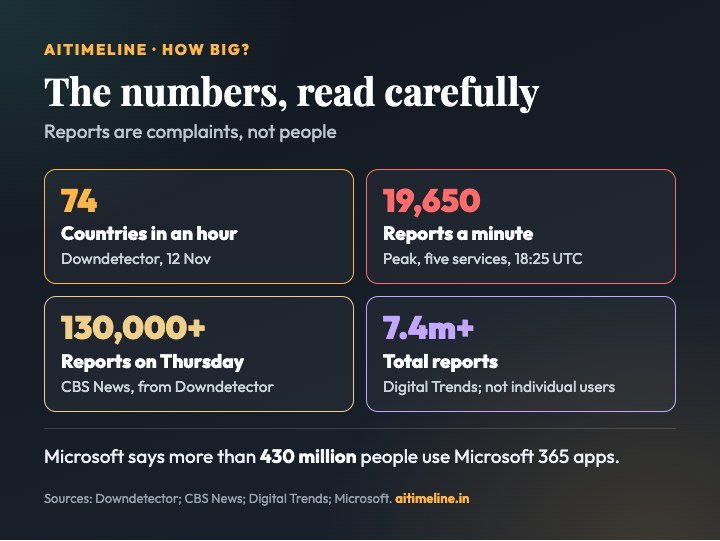
| Figure | Source | What it measures |
|---|---|---|
| 74 countries and territories | Downdetector | Where reports came from within about an hour on 12 November |
| 19,650 a minute | Downdetector | Peak reports across five Microsoft services, 18:25 UTC |
| More than 130,000 | CBS News, from Downdetector | Reports about Microsoft on Thursday 12 November |
| More than 7.4 million | Digital Trends | Total outage reports worldwide; not individual users |
| More than 430 million | Microsoft | People who use Microsoft 365 apps; not the number affected |
The brief we worked from attributed the 7.4 million total and a peak “approaching 20,000 a minute” to Reuters. The per-minute peak comes from Downdetector itself (19,650), and we could read the 7.4 million figure only in Digital Trends, which cites Reuters for some of its reporting.
How Microsoft Fixed It
Recovery was slower than diagnosis.
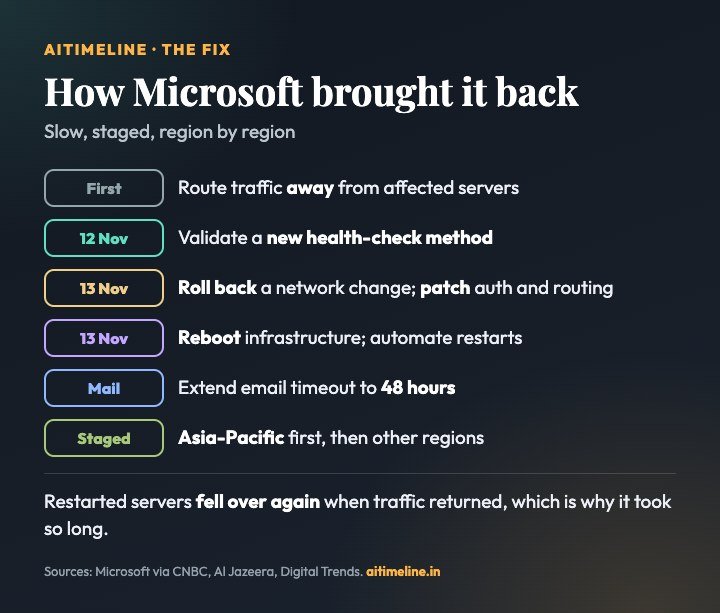
Two details explain the length. First, servers that were simply restarted fell over again as soon as traffic came back, so Microsoft had to change how it judged server health before it could keep them in service. Second, the rest of the internet’s mail servers kept retrying messages they could not deliver, so when Exchange Online came back it faced a wall of queued mail. Extending the timeout to 48 hours protected those messages but meant clearing the backlog took time. The brief we worked from also said Microsoft added virtual machines and restricted certain traffic; we found reports of traffic being routed away from affected servers, but not of extra virtual machines.
Not the First: Earlier Microsoft Outages, and CrowdStrike
The 2024 crash was a different kind of failure.
| Date | Incident | Cause | Attack? |
|---|---|---|---|
| 25 Jan 2023 | Teams, Outlook, Azure disrupted worldwide | IP address change on a WAN router | No |
| Jun 2023 | Outlook on the web, OneDrive, Azure portal | Layer-7 DDoS by Storm-1359 | Yes |
| 19 Jul 2024 | CrowdStrike: 8.5 million Windows PCs crash | Faulty third-party security update | No |
| 30 Jul 2024 | Azure and some Microsoft 365 services | DDoS, worsened by an error in defences | Yes |
| 29 Oct 2025 | Azure, Microsoft 365, Xbox via Azure Front Door | Inadvertent configuration change | No |
| 22 Jan 2026 | Microsoft 365 in North America, about 10 hours | Reduced capacity during maintenance | No |
| 12-14 Nov 2026 | Microsoft 365 worldwide, well over 24 hours | Network-capacity upgrade fault exposed by a network change | No |
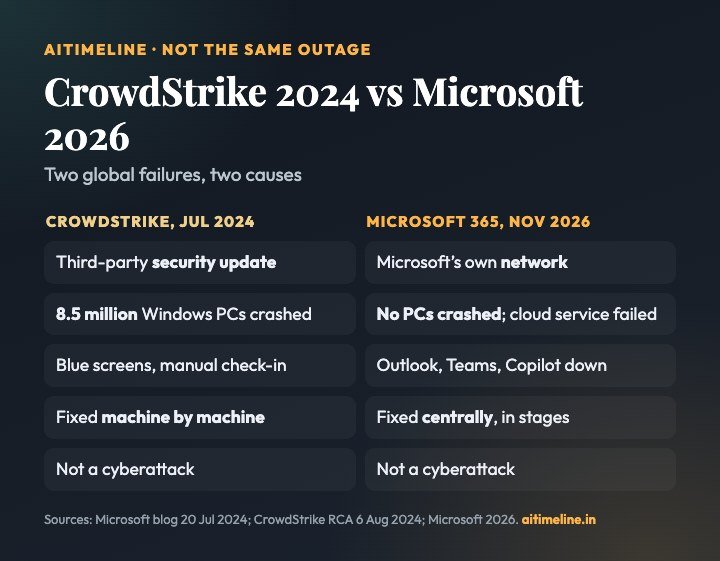
The CrowdStrike crash of 19 July 2024 is the outage most people remember, and the one Australia’s Tony Burke reached for in November 2026. But it was a different kind of failure. A security company’s faulty content update crashed Windows computers themselves, about 8.5 million of them by Microsoft’s estimate, and each had to be fixed by hand. In November 2026 no computer crashed: Microsoft’s cloud service failed, and Microsoft fixed it centrally. The closest precedent is January 2023, when a single router change inside Microsoft’s network disrupted Teams and Outlook worldwide. For an earlier story of how a dominant communications platform can stumble, see our history of BlackBerry’s rise and fall.
CrowdStrike 2024 vs Microsoft 2026
Lessons from the Microsoft Outage
- Concentration is a risk: when one provider runs email, calendars, meetings and files for governments, hospitals and airlines at once, its failure is everyone’s failure.
- Network changes need stronger checks: January 2023, October 2025 and November 2026 all began with a change inside the provider’s own network.
- Safety systems can amplify failure: health checks meant to protect users pulled servers out and overloaded the rest.
- Keep a backup channel: the organisations that coped best had phone lines, independent email or simple manual procedures ready.
- Restored is not normal: after the all-clear, check that queued mail arrived and that calendars and connected tools work.
Questions of digital dependence run through much of our technology coverage, from India’s data protection law to the risks in smart home devices and the growing reach of AI systems traced in our AI regulation timeline.
Facts at a Glance
| Question | Answer |
|---|---|
| When did it begin? | 12 November 2026, 16:17 UTC (Exchange Online) |
| When was restoration announced? | Early on 14 November 2026 |
| How long? | Well over 24 hours; about a day and a half to the all-clear |
| Most affected | Exchange Online, Outlook, Teams calendars, Copilot |
| Cause | Fault from an earlier network-capacity upgrade, exposed by a later network change |
| Cyberattack? | No, according to Microsoft |
| Reach | 74 countries and territories within an hour (Downdetector) |
| Incident ID | MO1550821 (Microsoft 365 admin centre) |
| Same as CrowdStrike 2024? | No; that was a third-party update that crashed Windows PCs |
Explore More Timelines
People Also Ask
Frequently Asked Questions
Based on Microsoft statements and reporting to 14 November 2026.
⚠️ Editorial Note
This timeline reflects information available on 14 November 2026. Microsoft had not published its post-incident review, so the cause and recovery sequence are as Microsoft described them in status updates and statements reported by CNBC, AP, CBS, Al Jazeera, Digital Trends and others; they are not independent findings. Downdetector figures are user reports, not counts of affected people. Checking the record, we adjusted the brief we worked from: Microsoft dates the start to 16:17 UTC; the first public acknowledgment came just before 18:00 GMT, consistent with but not confirmed as 5:54 pm; the 19,650-a-minute peak is Downdetector’s own figure; and the police force affected was reported only as “British police”. We could not confirm the brief’s references to an overwhelmed secure-connection process, added virtual machines, a 13-minute gap before the warning widened, or an Indian brokerage, and left them out. We could not open the Reuters and Times of India reports directly; Reuters material is cited where other outlets quoted it. This page is not technical or legal advice.
Related Reading on AiTimeline
Sources & further reading
Every dated entry above was checked against these references. Last reviewed 14 November 2026.
- Microsoft's longest outage in years is finally over. Here's what went wrong
- Microsoft apologizes for massive outage that took down Outlook and other 365 services
- Microsoft says Microsoft 365 services fully restored after Outlook, Teams and Copilot impacted
- Microsoft says it has restored service and addressed underlying issue after worldwide outage
- Microsoft hit by global outages: What happened and why?
- Microsoft 365 outage drags into Day 2, hits IndiGo, Air India and Akasa Air
- Microsoft Outage Ends: Outlook, Teams and Copilot Services Fully Restored Worldwide
- Microsoft 365 outage drags on for nearly 10 hours
- Helping our customers through the CrowdStrike outage
- Channel File 291 Incident: Root Cause Analysis is Available
- Microsoft Response to Layer 7 Distributed Denial of Service (DDoS) Attacks
- Azure status history